


 +100宝石





产品功能
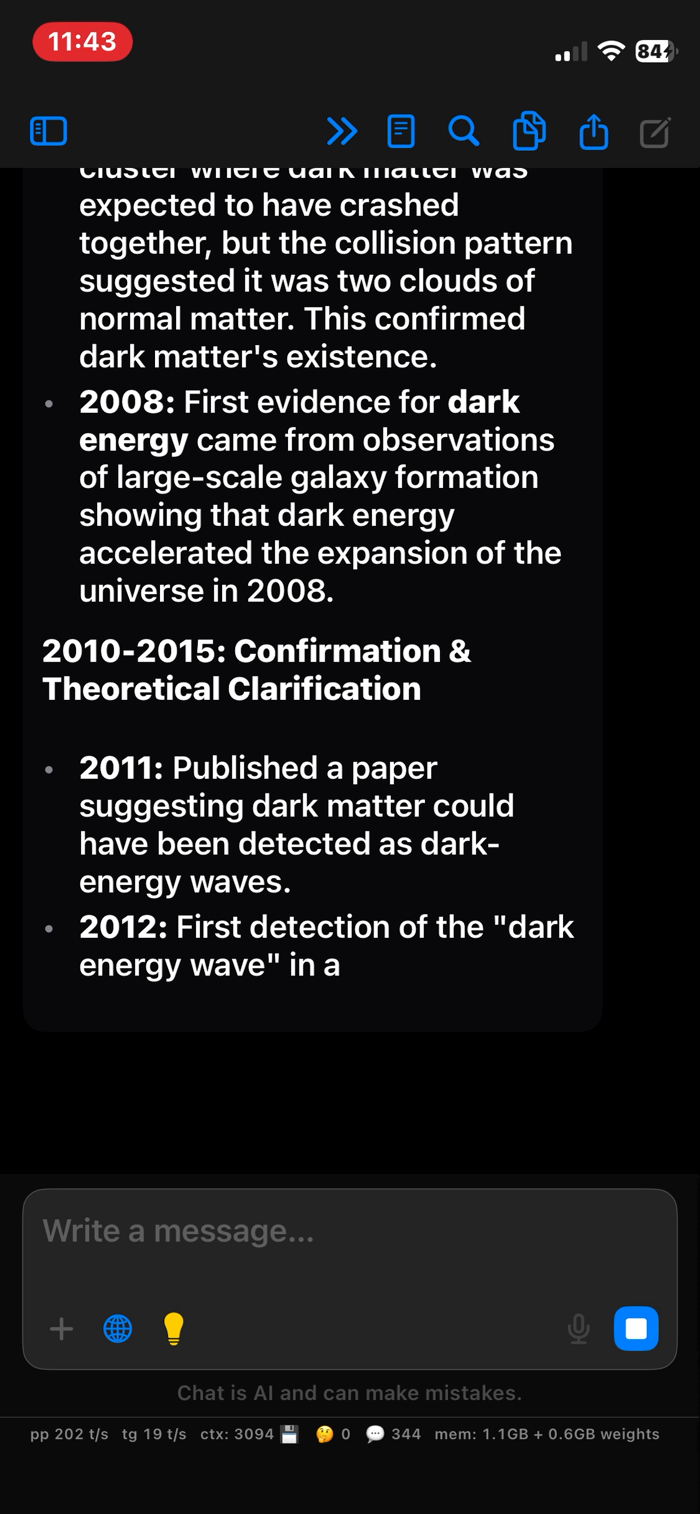
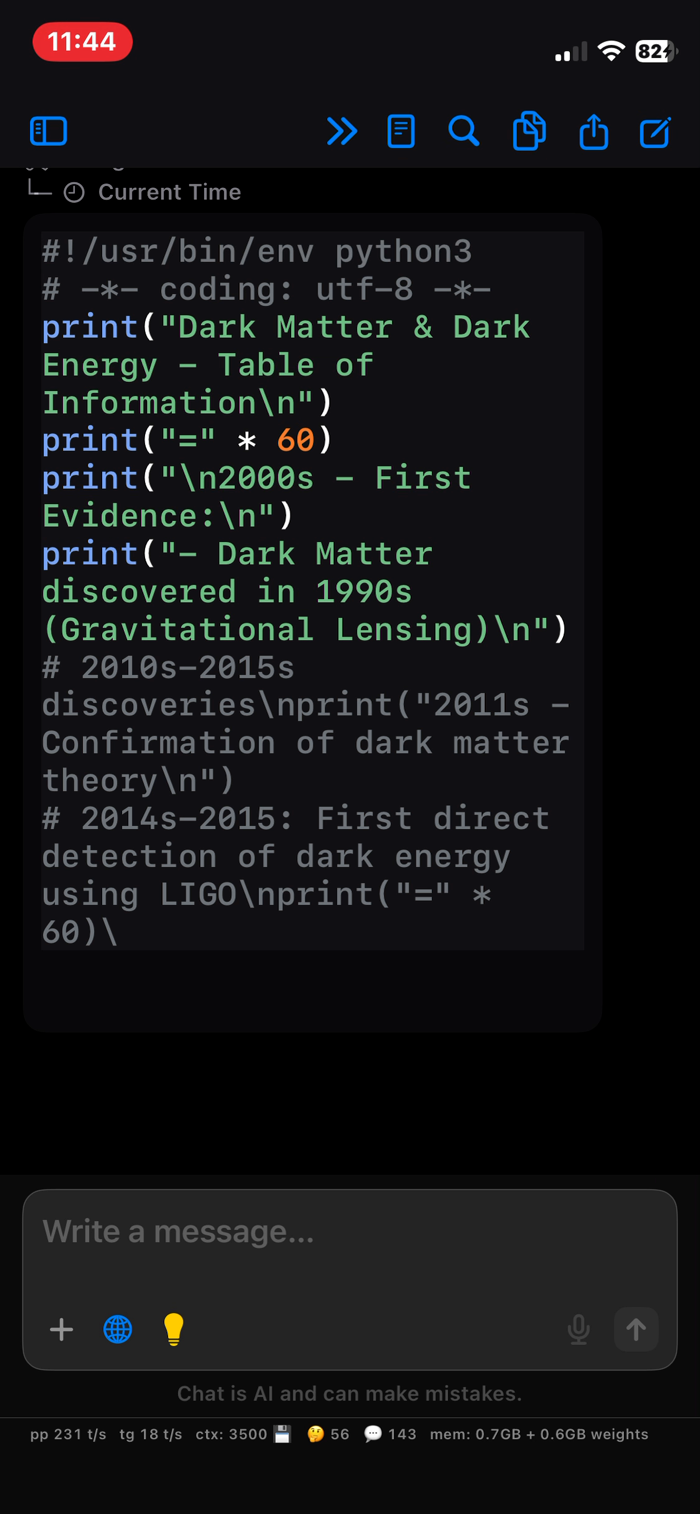
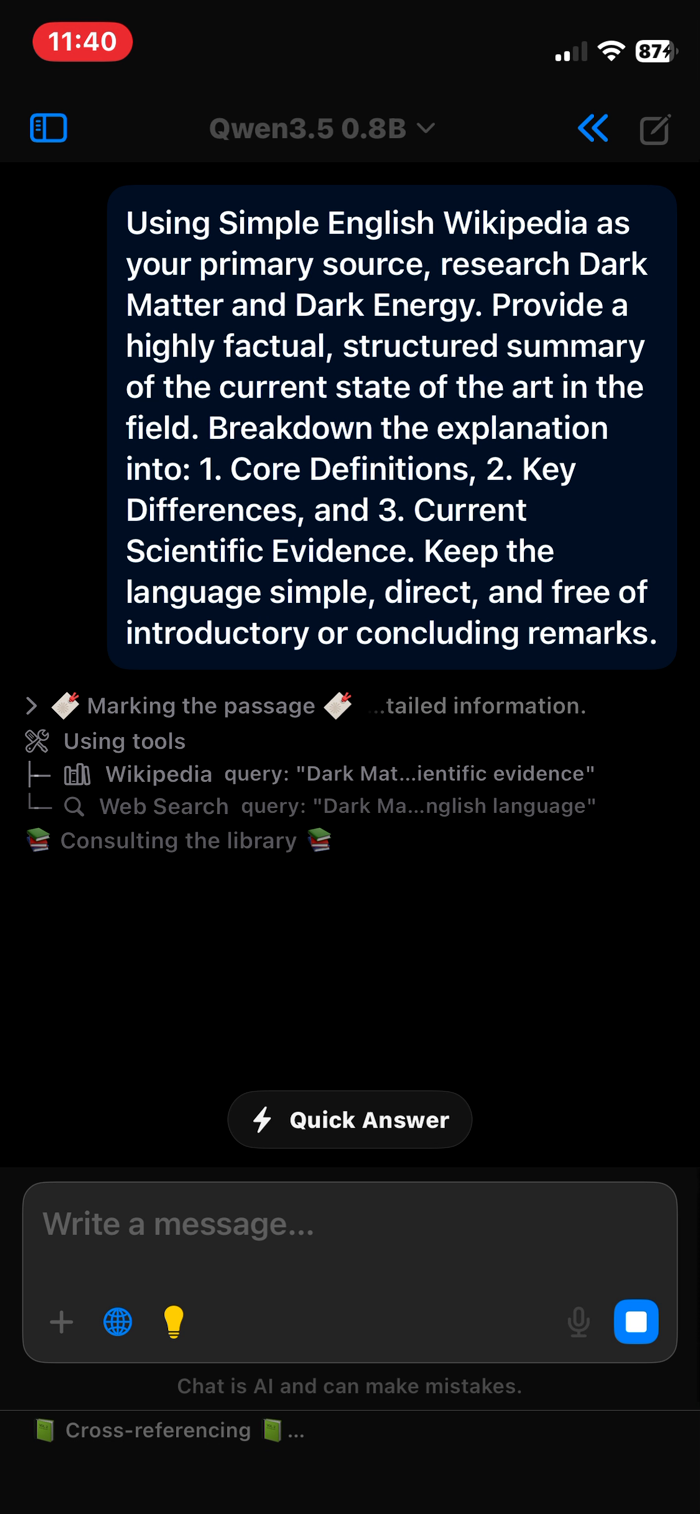
Gadeon runs Qwen3.5 and QwenPaw hybrid language models entirely on your device's Apple Neural Engine, using Core ML as its only framework dependency. There's no C, no Python, and no cloud calls: every token is generated locally, keeping your conversations private.
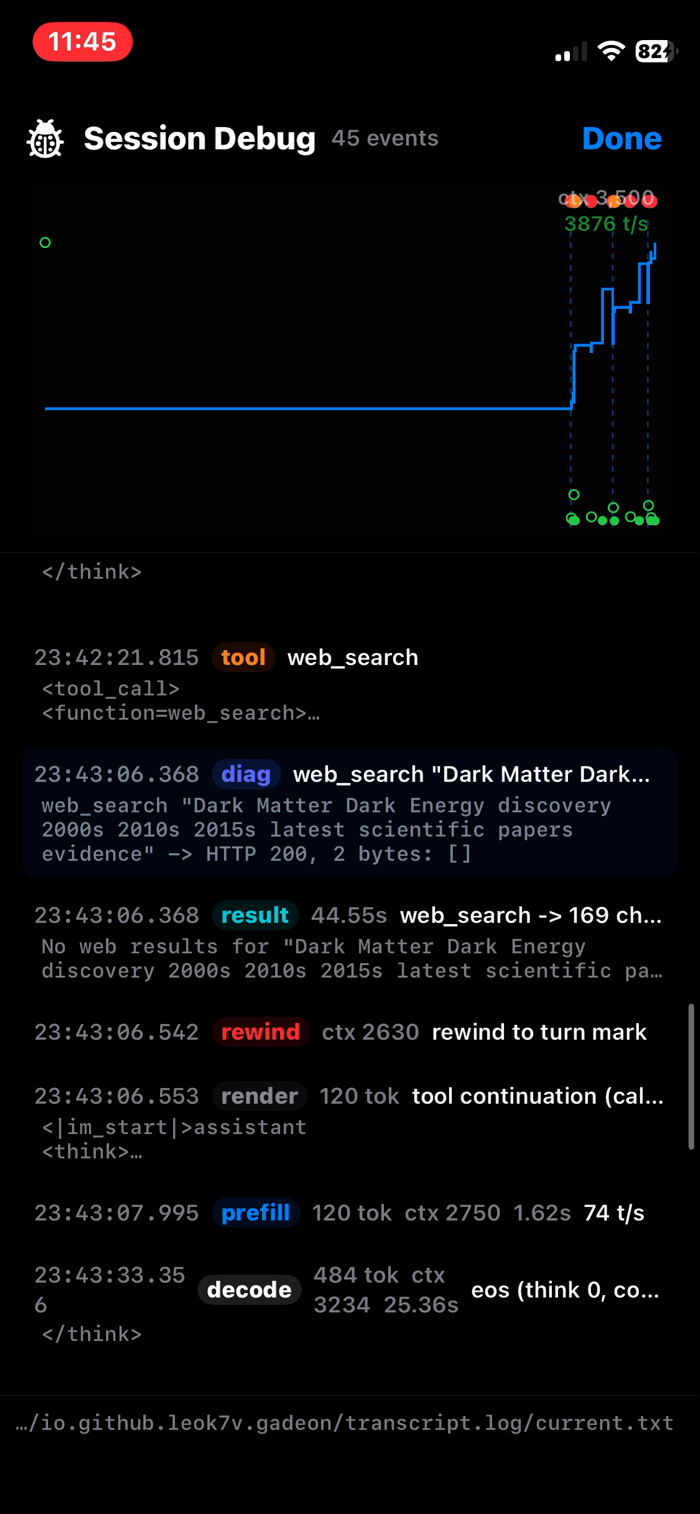
Under the hood, these models mix Gated DeltaNet recurrent layers with a smaller number of attention layers. Gadeon compiles that hybrid architecture directly onto the Neural Engine's dataflow accelerator, so both prompt processing (prefill) and token generation (decode) run on-chip instead of falling back to the CPU or GPU. On an Apple Silicon Mac, prefill measures roughly 2 to 2.4 times faster and about 4.4 times more energy-efficient per token than a Metal GPU baseline, while leaving the GPU free for other work.
Conversations in Gadeon are append-only: each turn extends the model's fixed-size recurrent state instead of re-processing the entire chat history, so response latency doesn't grow as a conversation gets longer. The app can also roll back to an earlier point in a conversation, dropping reasoning traces or replaying tool calls in a clean form without reprocessing everything from scratch.
For ternary-quantized models, Gadeon switches to a pure-Swift Metal GPU backend behind the same session and tokenizer interface, so both compute paths feel identical from the chat UI.
Gadeon is a proof of concept for bringing Gated DeltaNet hybrid models to the Neural Engine through Core ML - built to explore what's possible on Apple's own silicon.
分享「」体验,参与「」抽奖!
分享 1~3 张你对这个产品最满意的截图或效果图
分享「」体验,参与「」抽奖!
用你的故事点亮社区✨!你的真实体验,将会永久展示在 官方主页 📌,为其他朋友提供宝贵参考 💡。立即分享吧!🚀
请为产品评分
请选择问题回答,为大家提供宝贵参考
选择要回答的问题
温馨提示
你尚未上传产品截图。
上传截图可立即获得宝石积分奖励!
如果你赶时间,也可稍后修改评论,补上截图领取宝石。
温馨提醒
你尚未添加产品截图
⚠️ 不添加截图将降低抽奖权重

感谢参加,你已成功参加!
为了确保你能及时收到审核结果和领奖码通知
扫描二维码关注 Mergeek 公众号
在后台回复 「获奖通知」
完成上述操作,即可保障奖励发放成功


用户评价
立即分享产品体验
你的真实体验,为其他用户提供宝贵参考
💎 分享获得宝石
【分享体验 · 获得宝石 · 增加抽奖机会】
将你的产品体验分享给更多人,获得更多宝石奖励!
💎 宝石奖励
每当有用户点击你分享的体验链接并点赞"对我有用",你将获得:
🔗 如何分享
复制下方专属链接,分享到社交媒体、群聊或好友:
💡 小贴士
分享时可以添加你的个人推荐语,让更多人了解这款产品的优点!
示例分享文案:
"推荐一款我最近体验过的应用,界面设计很精美,功能也很实用。有兴趣的朋友可以看看我的详细体验评价~"
关注 Mergeek 公众号
领奖遇到问题?联系小门助手